· iWork Technologies Team · Thought Leadership
Brooks' Law in Multi-Agent Engineering Teams: The Reviewer Is the New Constraint
Adding AI coding agents to a team adds throughput without adding meetings. It does add review load, and that is where Brooks' Law comes back. Here is how to structure a team around it.
Earlier this year we asked whether AI had finally broken Brooks’ Law. Our answer in The Mythical Man-Month Re-Opened was “yes and no”: agents change the arithmetic of communication and ramp-up, but the hard parts of building software do not disappear.
This follow-up gets more specific. Once you put several AI coding agents into a real team, where does the overhead go? Our view, from working this way every day: it moves from conversation to review. The constraint is no longer how many people need to talk. It is how many senior people can approve what gets built.
A quick recap of the law
Fred Brooks observed that adding people to a late software project makes it later. Two forces drive it:
- Ramp-up. New people need time to learn the system, and that time comes out of the people who already know it.
- Communication paths. In a team of n people, the number of pairwise channels is n(n-1)/2. Five people have ten channels. Ten people have 45. Coordination cost grows much faster than headcount.
Both forces assume every new contributor is a peer who must be kept in sync with every other peer.
What changes when agents join
AI coding agents such as Claude Code and OpenAI Codex do not join the team the way a new hire does.
They do not need to talk to each other. An agent working on the billing module does not need a standup with the agent writing tests for search. They do not need lunch-and-learns or a buddy for their first month. They read the repository, the task brief and the conventions you give them, and they start.
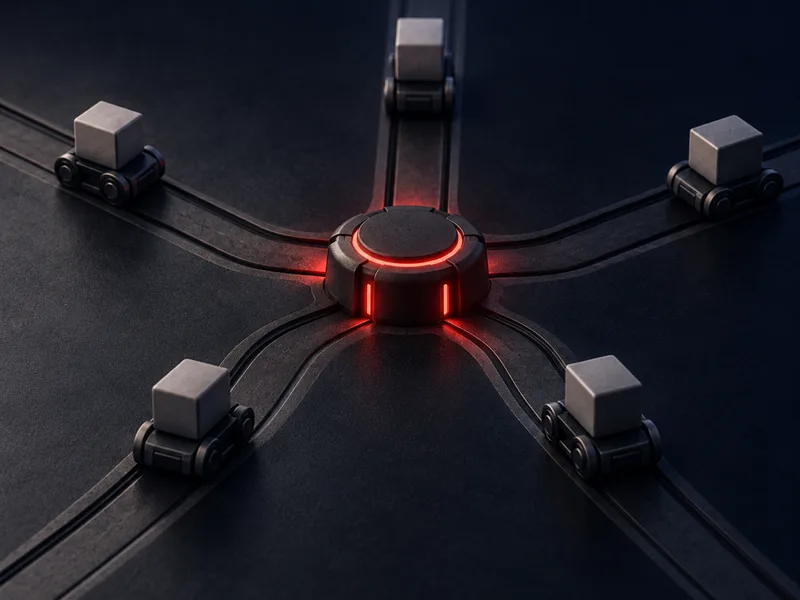
So the communication graph does not look like a mesh. It looks like a star. Each agent connects to the engineer directing it, and to nothing else.
That is the good news. Add an agent and you add throughput without adding a single meeting.
Where the paths reappear
The star has a center, and every edge ends there.
Every agent’s output has to be read by a person who understands the system well enough to say “yes, this is right” or “no, this breaks an assumption you could not see.” That person is the hub. If one senior engineer directs four agents, they now carry four streams of review, four sets of context and four places where a subtle mistake could slip in.
Look at it as a graph and the cost has not vanished. It has concentrated:
- Review becomes the shared resource. Agents contend for it the way people used to contend for meeting time.
- Context switching moves to the reviewer. The agent holds no state between tasks that the reviewer can rely on. The reviewer must rebuild context for each PR.
- Integration risk grows with parallelism. Each agent’s change can be correct on its own and wrong in combination. Someone has to see the whole.
Brooks’ insight survives in a new form: adding agents to a team whose reviewers are already full makes delivery slower, not faster. Work piles up waiting for approval, branches drift, and the changes that do merge get less scrutiny than they deserve.
Throughput is cheap. Judgment is not.
The practical consequence is a change in what you staff for.
In a traditional team, you add engineers to add output. In a multi-agent team, output is the cheap part. What you need more of is judgment: people who can decompose work, set constraints, read a diff critically and own the decision to ship.
That is why we define “up to 10x engineering velocity” carefully. It means shipped, reviewed work per engineer. Unreviewed agent output is inventory, not velocity. And it says nothing about calendar time, which still depends on scope, integrations and how quickly decisions come back.
How to structure a team around the constraint
If the reviewer is the constraint, design the team so review capacity, not agent count, sets the pace.
Keep the hub small and senior
Every agent should report to a named senior engineer who reviews its work. Pick a ratio of agents to reviewer that keeps the review load manageable, and treat it as a limit, not a target.
Decompose before you parallelize
The senior’s most valuable work happens before any agent runs. Split features into tasks that are small, independent and testable in isolation. Good decomposition reduces the integration risk that comes with parallel agents.
Separate architecture from implementation
One person should own the design decisions that cut across workstreams: data models, service boundaries, the review standard itself. Without that, several agents and several reviewers will each make locally sensible choices that do not fit together.
Push quality left with tests
Tests written or approved by a senior before implementation turn review from “is this right?” into “does this match the agreed contract?” That is faster to answer and harder to fake.
Limit work in progress
Do not start more agent tasks than your reviewers can finish. A queue of unreviewed PRs is the multi-agent version of adding people to a late project.
What this looks like in a pod
Our AI Velocity Pods follow this shape directly.
- A tech lead owns architecture decisions, the review standard and the link to your roadmap.
- Four senior engineers each direct AI coding agents and review every change those agents draft.
- Agents draft code, tests, PRs and deploy steps inside your repos and CI/CD, with scoped access only.
The number of people who talk to each other stays small: five, with ten channels between them, which is a team size Brooks would recognise as workable. The agents multiply what each senior can produce without multiplying the coordination.
Two more choices keep the constraint in check. Seniors review agent output before it reaches your team, so your engineers see finished, tested pull requests and your own review queue does not grow. And when the roadmap grows, the lever is more senior reviewers (extra seniors are $2.5K/mo each on the Growth Core team), not more unsupervised agents.
The law, restated
Brooks’ Law was never really about headcount. It was about the cost of keeping people in sync with each other.
Agents remove most of that cost between contributors. They concentrate what remains on the people who review and integrate the work. So a fair restatement for multi-agent teams might be:
Adding agents to a team whose reviewers are at capacity makes it later.
The answer is not to avoid agents. It is to treat senior review as the scarce resource it is, staff for it, and design the work so every agent’s output lands on a reviewer who has room to read it properly.
Where to start
If you are adding AI coding agents and your releases are not getting faster, look at the review queue first. That is usually where the time went.
Our Free AI Readiness Audit is a 30-minute call on your roadmap, codebase and delivery bottleneck, ending with a recommended team shape. To see how a pod is structured around review capacity, read about AI Velocity Pods.